Monitoring vs Observability: the same 3 AM incident, two paths
Monitoring tells you something is wrong. Observability tells you which hop of which request broke, and why. A system-design comparison with numbers, failure modes and a real streaming case.
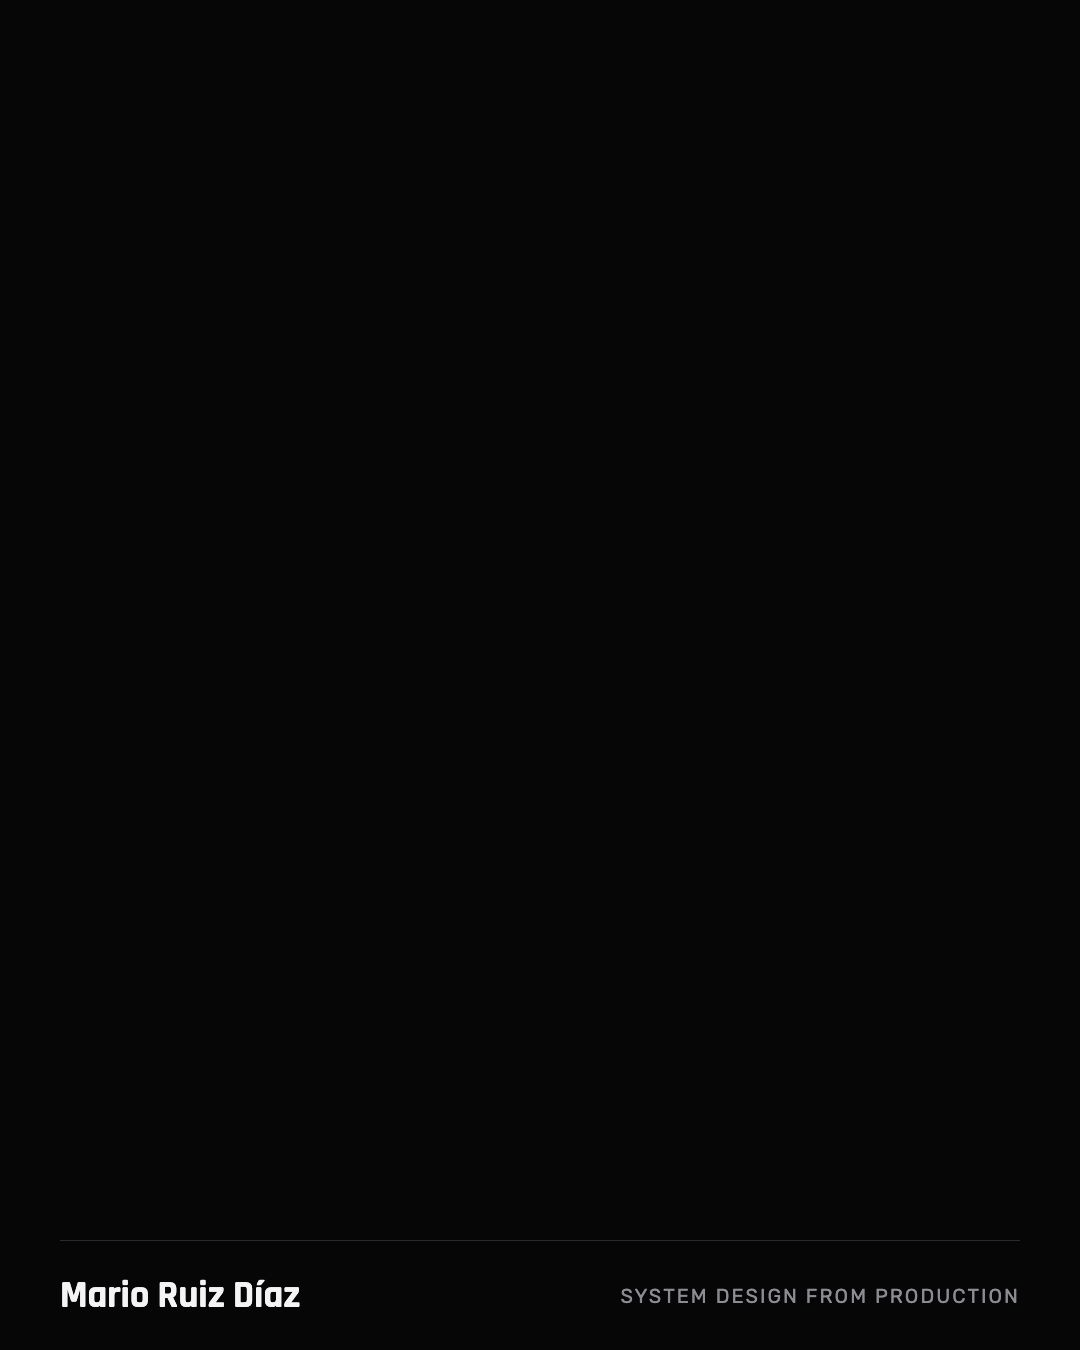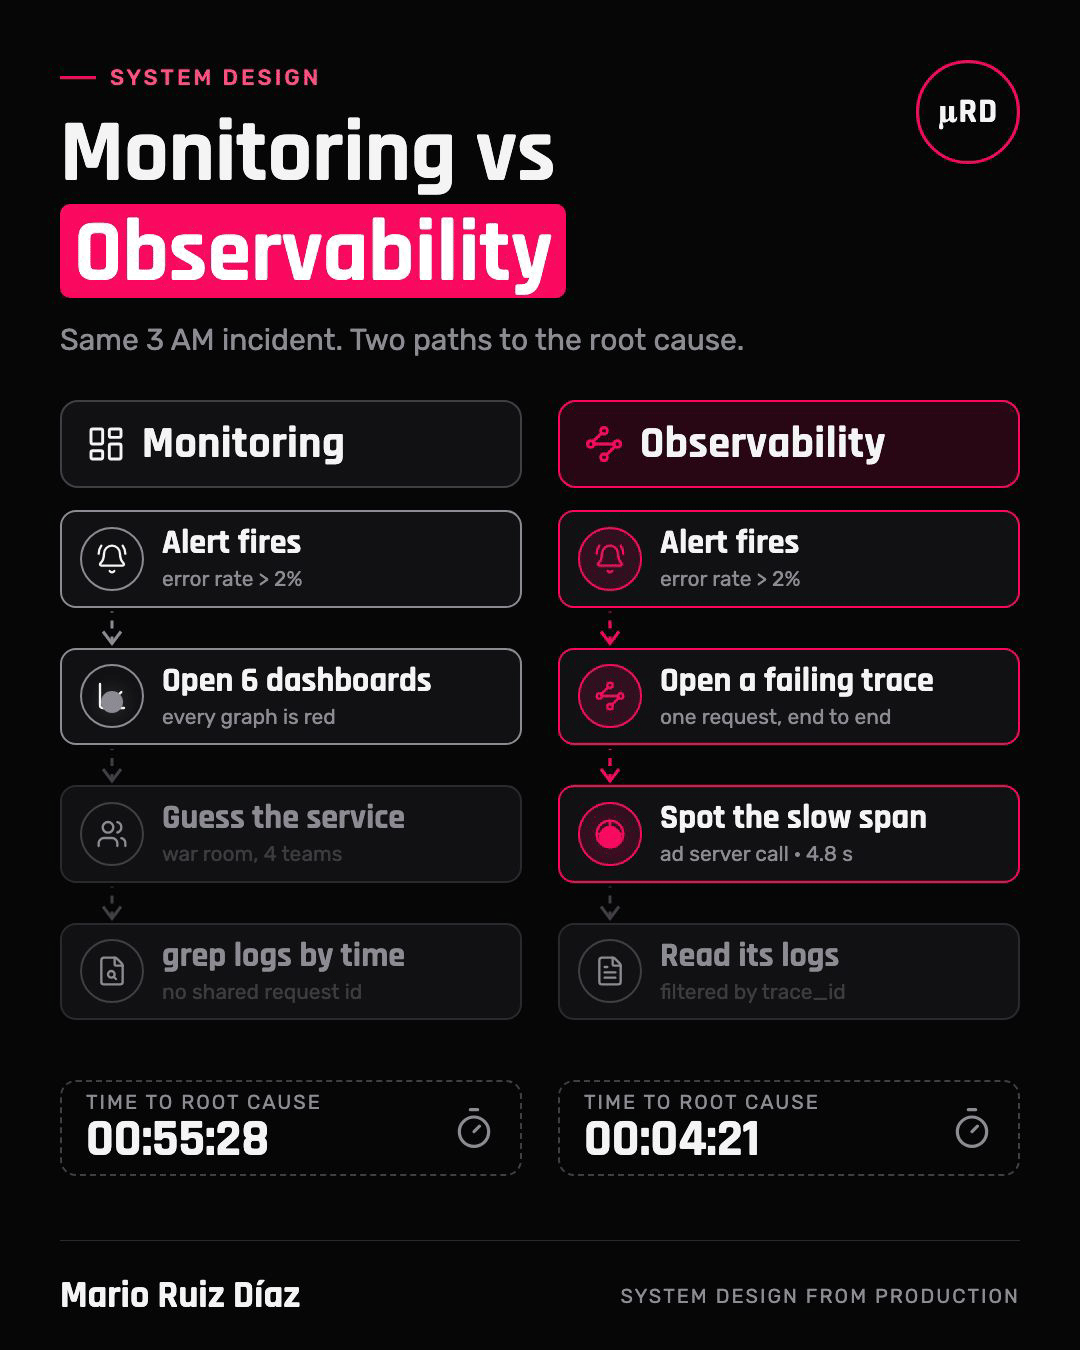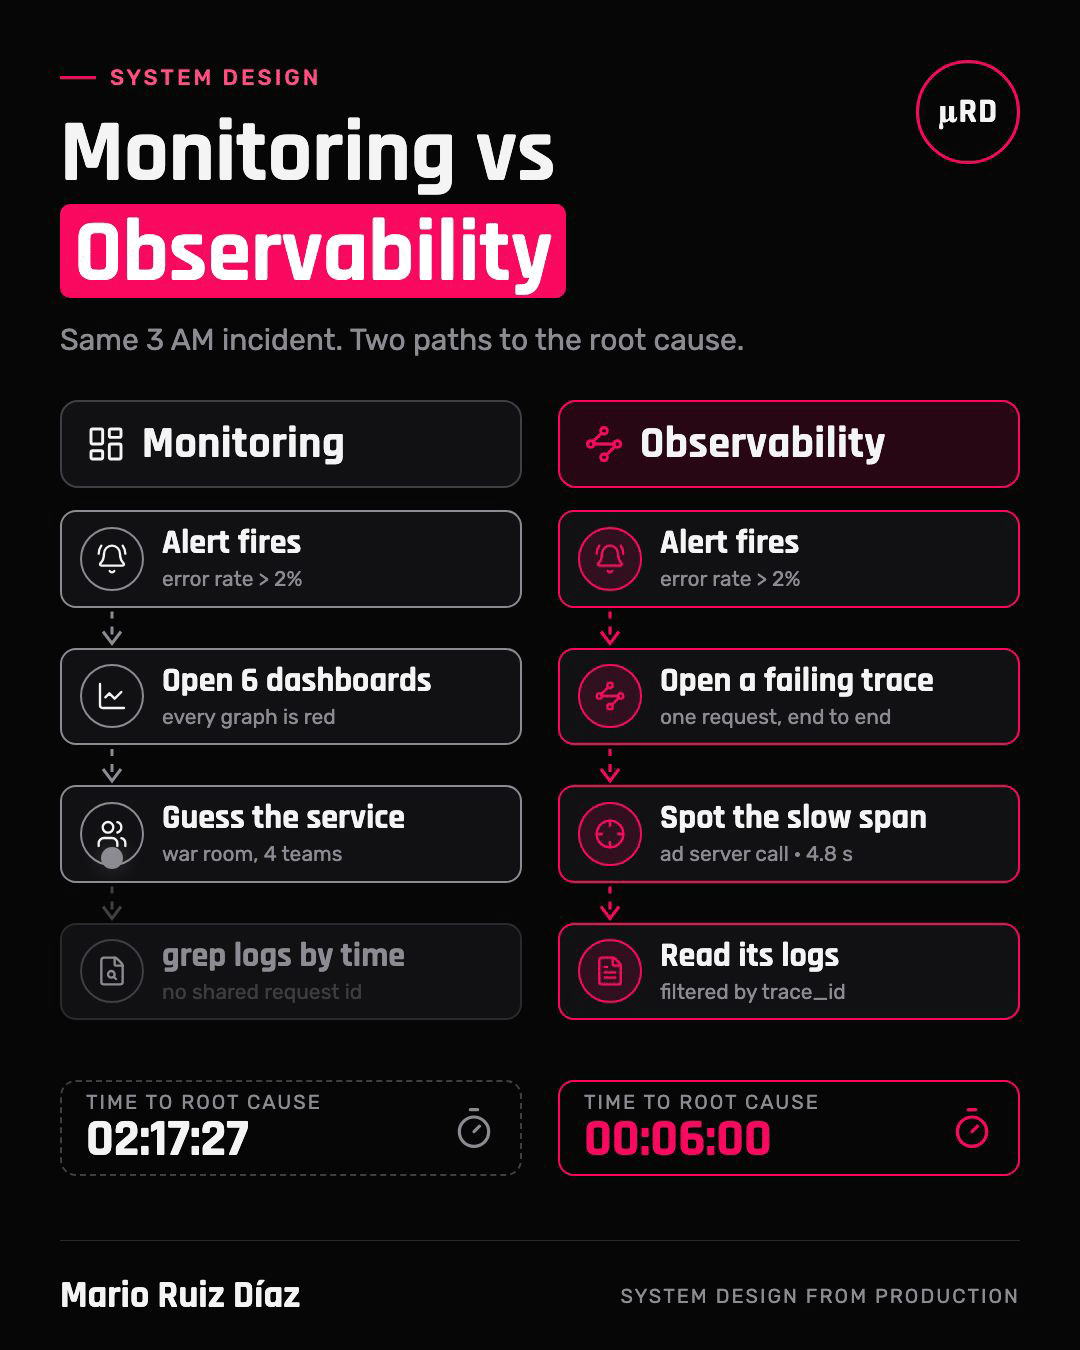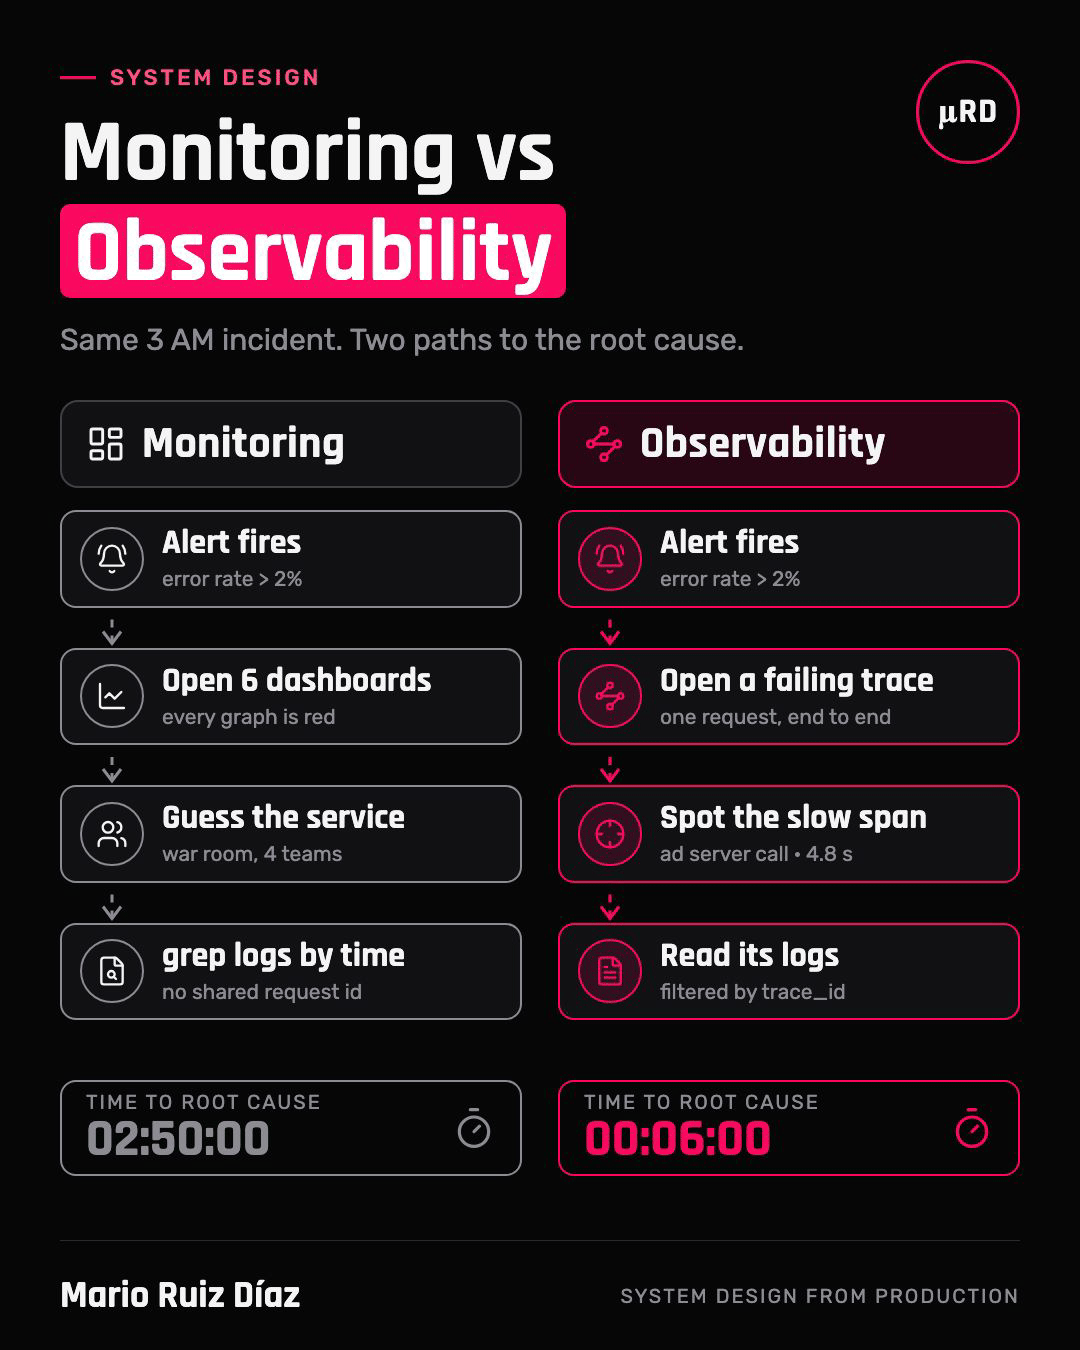
It is 3:07 AM. An alert fires: the error rate of the ad API crossed 2%. Two on-call engineers, two companies, the same incident.
The first one opens six dashboards. Every graph is red, because every service downstream of the failure is failing too. A war room forms with four teams, each one proving its own service is a victim, not the cause. Someone greps logs by timestamp across three log stores. Root cause lands a few hours later.
The second one clicks on a failing request, opens its trace, sees one span taking 4.8 seconds on a call to a third-party ad server, and jumps to the logs of that exact span. Root cause lands in minutes.
Same architecture. Same people. The difference is not tooling budget: it is whether the system was designed to explain itself. This article compares the three ways teams usually get there, what each one costs, and where each one breaks.
The problem: symptoms travel, causes hide
In a monolith, a failure is loud and close to its cause: one process, one stack trace, one log file. In a distributed system, a single user request crosses many services, queues and vendors. A failure at hop 3 surfaces as errors at hops 4, 5 and 6, and as latency at the edge.
That changes the question on-call needs to answer. "Is something wrong?" is easy; the alert already said so. The hard questions are:
- Where did this request degrade: which service, which hop, which dependency?
- Why: what was different about the failing requests (tenant, device, partner, payload, version)?
- What changed first: a deploy, a config flag, a vendor, a traffic shape?
Monitoring is built for questions you knew to ask in advance: CPU above 80%, error rate above 2%, queue depth above 10k. Observability is the property of a system that lets you ask new questions of it in production, without shipping new code. Monitoring is a feature you add; observability is a property you design.
Requirements
A useful bar for an incident-response design:
- Detect user-visible degradation in under a minute (this is still monitoring's job).
- Localize the failing hop for any single request, including asynchronous hops through queues and third parties.
- Explain the failure with business context: which tenant, partner, device or endpoint is affected.
- Correlate the three signals: from a metric spike to example traces, from a trace to its logs.
- Stay affordable: telemetry cost should grow slower than traffic.
Scale estimate
Numbers make the trade-offs concrete. Take a mid-size streaming backend (illustrative, not any specific company):
| Input | Value |
|---|---|
| Peak requests at the edge | 3,000 req/s |
| Services touched per request | 8 (some via queues) |
| Spans per request | ~12 |
| Average span size | ~1 KB |
| Log lines per hop | ~5, ~300 bytes each |
That gives:
- Spans: 3,000 × 12 = 36,000 spans/s → ~36 MB/s → ~3 TB/day if you keep everything.
- Logs: 3,000 × 8 × 5 = 120,000 lines/s → ~36 MB/s → another ~3 TB/day.
- Metrics cardinality: tag a request counter by device (50) × partner (200) × endpoint (30) × status (5) and you get 1.5 million time series for a single metric. Most metrics backends price per series; this is where budgets die.
Three design consequences follow directly from the arithmetic:
- High-cardinality context belongs on spans and logs, not on metrics. Metrics stay low-cardinality (service, endpoint, status); partner and device live as span tags you can filter on demand.
- You cannot keep every trace. You need a sampling strategy that keeps the interesting ones (errors, slow requests) at 100% and a small baseline of the rest.
- Logs must stop duplicating context. If the query string, tenant and device are written once on the root span, every log line no longer needs to repeat them.
Approach 1: Monitoring (metrics, thresholds, dashboards)
Scroll sideways to see the full diagram →
Each service emits aggregated metrics (RED: rate, errors, duration; USE for resources). An alerting engine evaluates thresholds and pages someone. Dashboards show trends. Logs exist, but they live in separate stores and are searched by timestamp and service name.
Where it shines
- Cheap and fast. Aggregates compress millions of requests into a few numbers per minute.
- Excellent for detection and for SLOs: burn-rate alerts on error budgets are still the best way to wake someone up for the right reasons.
- Easy to own: every team understands a dashboard.
Where it breaks
- Aggregates erase the individual request. A p99 latency graph tells you 1% of requests are slow; it cannot tell you which ones, or what they have in common.
- Cascading failures paint every dashboard red. Downstream victims and the upstream cause look identical.
- Correlation is manual. Joining a metric spike to log lines by timestamp across services, clock skew included, is guesswork under pressure.
Approach 2: Correlated logs
Scroll sideways to see the full diagram →
The middle ground most teams reach first. The edge assigns a correlation ID to every request; each service logs it in structured JSON and forwards it in headers. Now you can query one ID and get every log line that request produced.
Where it shines
- Low barrier: a middleware and a logging convention.
- A huge step from timestamp grepping. One ID returns the whole story, if everyone logged it.
Where it breaks
- No causality and no timing. You get a pile of lines, not a tree. Which call was the parent? Where did the 4.8 seconds go? You reconstruct it by reading.
- Gaps are silent. One service that forgets to forward the ID, one queue consumer that drops it, and the trail ends without an error.
- Cost scales with verbosity. To make logs explain latency, teams log more, and log volume is already the biggest line on the telemetry bill.
Approach 3: Distributed tracing with context propagation
Scroll sideways to see the full diagram →
Every request carries a trace context (the W3C traceparent header: trace id, parent span id, sampling flag). Each service creates spans: timed operations with a parent, tags and status. Spans are exported to a collector and assembled into a tree: the full request, hop by hop, with the time spent in each one. Logs are emitted with the active trace_id and span_id, so they attach to the exact operation that produced them. Metrics carry exemplars: a link from a spike to example traces.
Anatomy of one trace
Scroll sideways to see the full diagram →
On the left, the request moves through services A to E and every call carries the trace context. On the right, the same request as spans on a timeline. The root span A is the request as the client saw it: 5.1 seconds. Its children show where those seconds went: 12 ms in Redis, 4.8 s waiting on a third-party ad server that timed out. Every span carries the same trace_id and the id of its parent, and the business tags (partner, device) set on the root are queryable on the whole trace. That is what makes any single span a door into the full story: start from the slow span, the worker that ran after the response or one log line, and you land on the same request, end to end. The context that travels is small (a trace id, a parent id, a sampling flag); the history is reassembled by the backend from every span that shares the id.
Where it shines
- Localization is visual. The slow or failing span is highlighted; you do not reconstruct anything.
- Business context on spans (partner, device, endpoint, status) turns every trace into a queryable event: "all failing ad requests for partner X on TV devices since the 2:50 deploy."
- All three signals join on one key. Metric → exemplar trace → span → its logs.
Where it breaks
- Propagation gaps. Context flows automatically over HTTP with standard instrumentation. It does not cross queues, batch jobs or third-party platforms unless you carry it explicitly (see failure modes below).
- Sampling loses the needle. Head-based sampling (decide at the edge, e.g. keep 10%) drops 90% of the rare errors you most need.
- Instrumentation drift. Spans and tags are code; without conventions, every team names things differently and cross-service queries fail.
- Cost, again. At ~3 TB/day of raw spans, keeping everything is rarely justified.
Side by side
| Monitoring | Correlated logs | Distributed tracing | |
|---|---|---|---|
| Answers | Is something wrong? | What did this request log? | Where and why did this request fail? |
| Unit | Aggregate per minute | Log line | Span tree per request |
| Async hops | Invisible | Only if ID is forwarded | Only if context is propagated |
| Timing per hop | No | Reconstructed by hand | Native |
| Cardinality | Must stay low | High, costly at volume | High, on spans |
| Typical cost driver | Series count | Log volume | Span volume (sampling) |
| Best at | Detection, SLOs | Debugging a known request | Localization, unknown failures |
They are not alternatives. A mature system uses metrics to detect, traces to localize and logs to explain, joined by a shared trace id. The design work is in the joins.
Choosing a backend
Instrument with OpenTelemetry first: it is the vendor-neutral standard for traces, metrics and logs, so the backend becomes a configuration choice you can change later. Then pick where the data goes:
| Backend | Model | Strong at | Watch out for |
|---|---|---|---|
| Datadog APM | SaaS, all-in-one | APM, logs, RUM and infra in one place; strong auto-instrumentation | Cost grows with hosts, ingested spans and indexed logs |
| Honeycomb | SaaS | Fast queries over high-cardinality data; tail sampling with Refinery | Not an infra monitoring suite; pair it with metrics tooling |
| Grafana Tempo + Loki + Mimir | Open source or Grafana Cloud | Cheap trace storage on object storage; TraceQL; one Grafana for all signals | You operate it, unless you pay for Grafana Cloud |
| Jaeger | Open source (CNCF) | Solid, self-hosted tracing | Tracing only; metrics, logs and alerting are on you |
| AWS X-Ray / CloudWatch | AWS-native | Built into Lambda, API Gateway and SQS | Weaker outside AWS; multi-cloud gets awkward |
New Relic, Dynatrace and Elastic APM sit in the same space as Datadog. The choice matters less than propagation and tagging: a perfect backend cannot stitch together spans that never shared a trace id.
Failure modes of observability itself
The tricky part is not adding a tracing SDK. It is everything that silently breaks the chain.
Scroll sideways to see the full diagram →
- Queues drop the context. HTTP headers do not travel inside an SQS, SNS or Kafka message. Inject the trace context into message attributes or headers on publish and extract it on consume. For batch consumers that process 100 messages in one execution, one parent is wrong: create a span per message, or use span links to point at each producer.
- Third-party platforms start a new trace. A vendor that calls you back (a transcoder, a payment provider, an ad server) will not forward your headers. If its API accepts metadata, inject the trace context into the payload and extract it in the callback handler. The external step then shows up inside the same trace instead of as an orphan.
- Head sampling discards the errors. Decide at the end, not the start: tail-based sampling in the collector keeps 100% of traces with an error or above a latency threshold, plus 1-5% of the rest. With the numbers above, that turns ~3 TB/day into well under 200 GB while keeping every incident.
- Metric cardinality explodes. A well-meaning tag (user id, full URL, partner × device) on a metric multiplies series. Enforce an allow-list of metric tags; push everything else to spans.
- Clock skew lies about latency. Spans from different hosts carry different clocks. Trust durations measured within a span; be skeptical of gaps between spans on different hosts.
- Sensitive data in tags. Spans are queryable by many people. Redact query strings and payload fields at the SDK or collector, not in each service.
Real-world case: tracing ad delivery at Pluto TV
Situation. Pluto TV is a free, ad-supported streaming service: every ad break is revenue. The services that decide, fetch and prepare ads ran on AWS Lambda and containers, communicated over HTTP, SQS and SNS, called third-party VAST ad servers and handed creatives to Hybrik, an external transcoding platform. When something broke, the evidence was split between Loggly and CloudWatch, and engineers reconstructed each request by hand, service by service. The asynchronous hops broke any simple correlation.
Task. Make a single ad request inspectable end to end, including the asynchronous and external hops, and make it the standard for the revenue services rather than a one-off.
Action.
- I proposed and led a distributed tracing initiative with Datadog APM, and started with a proof of concept on the hardest path, not the easiest: three services and a transcoding-status Lambda that exercised every propagation mechanism at once.
- Context was propagated over HTTP (adProxy → adRequester), over SQS message attributes (adProxy → adCollector) and over SNS notifications.
- Hybrik does not forward trace headers, so the trace context was injected into the job payload sent to Hybrik and extracted by the Lambda that handled its SNS callback. The external transcoding step stayed inside the same trace.
- Business tags (app, device, partner, endpoint, status) went on spans, so they became filters and metrics without extra instrumentation. Logs were attached to their parent span, and heavy fields such as query strings were written once on the root span instead of in every log line.
- Once the hardest path worked, the same conventions rolled out to more than 20 services, and Datadog RUM on the mobile, web and TV apps connected what viewers experienced to the backend traces behind it.
Result. One trace id held the complete history of an ad request, with errors highlighted at the trace level. Incident investigation went from manual, service-by-service reconstruction to a direct route to the failing hop, and the tracing and tagging conventions became the baseline for the revenue services.
The lesson I keep from it: prove observability on the path where correlation is hardest. If it works across a queue and a third-party platform, the synchronous services are easy.
Read the full case: how I traced Pluto TV's ad delivery end to end →
Where to start
You do not need a platform rewrite. In order:
- Adopt one context standard: W3C Trace Context via OpenTelemetry, so every language and vendor speaks the same header.
- Trace the revenue- or customer-critical path first, end to end, including its queues and vendors.
- Close the async gaps explicitly: message attributes on publish/consume, payload injection for third parties, span links for batches.
- Define the tag contract: a short list of business tags every span carries, and an allow-list for metric tags.
- Sample at the tail: keep every error and slow trace, a small baseline of the rest.
- Join the signals: trace id in every log line, exemplars on latency metrics.
- Review every incident with the trace open, and add the one signal you were missing.
The takeaway
Monitoring is how you find out. Observability is how you find where and why. Keep monitoring for detection and SLOs; design for observability by propagating context across every hop, putting business context on spans, sampling at the tail and joining metrics, traces and logs on one id. When the system can explain itself, a lower MTTR is a property of the architecture, not the heroics of whoever is on call.
References
- W3C Trace Context, the
traceparent/tracestatestandard. - OpenTelemetry: signals and sampling.
- Google SRE book: Monitoring Distributed Systems.
- Charity Majors, Liz Fong-Jones, George Miranda, Observability Engineering (O'Reilly, 2022).